Hours come back to your team
Work that is repetitive, rule-based and high-volume is where automation pays, and it is found by measuring the process you run today.
A document can hold the information your team needs while still requiring someone to copy it into a database. Norml builds extraction workflows for a defined set of forms, order documents or other recurring records. We agree the fields, test representative files and prepare structured results for review. Each result keeps a link to its source so someone can check the wording before accepting the value.
A few clients we’ve worked with

Turn agreed document fields into structured records with source references, validation checks and a review queue before the data enters your business systems.
The expensive mistake is automating the wrong step convincingly. The value is real, and it comes from measuring the process before building anything.
Work that is repetitive, rule-based and high-volume is where automation pays, and it is found by measuring the process you run today.
When the routine path runs itself, the next increase in volume does not need another person watching a queue.
An automated step nobody can verify is a liability, so the review point is part of the design rather than something bolted on later.
We scope the document families and output fields together. Supplier invoice processing and document classification can be separate stages when the intake requires them.
We specify names, data types and required fields before choosing the extraction model. The review record retains the supplied value alongside any normalized version, such as a date. Source file and page references help a reviewer resolve conflicting values or check a table entry.
Required-field, format and cross-field checks run after extraction. Missing values stay empty or flagged according to your rules. Available model confidence can help route review, but it does not replace validation or prove that a value is correct.
Airtable can hold the proposed values and review status. File identity, source version and destination record ID help prevent duplicate writes. Unreadable files, unsupported layouts and interrupted runs remain visible for an owner to resolve before data moves onward.
“Norml Studio's professionalism and responsiveness were impressive.”
“They were proactive in suggesting improvements we hadn't considered.”
“They delivered what they said they would, on time.”
“They focused on how to make our daily operations easier, not just on building features for the sake of it.”
“They understood that the app needed to be practical for someone sitting in a car, not just look good on a desktop.”
“Their level of dedication to the success of the project and GoPetZen's business as a whole is unique.”
Provide anonymized examples covering normal layouts, scans, multi-page files and known exceptions. We need permission to process the chosen content and an agreed retention policy for files and extracted results.
List the fields your team needs, acceptable formats and which source wins when values conflict. Identify tables, repeated sections and fields that must remain manual if they cannot be read reliably.
Name the reviewer, the acceptance action and the destination system. Decide whether this phase ends in Airtable or includes a separately tested write to another application.
We compare extracted values with checked examples and record where layouts, handwriting or scan quality affect the result. This establishes the supported scope and which cases require review.
We connect the intake, extraction model and review records. Normalization rules remain separate from source values, and retries use the processing record to avoid creating another accepted result.
We test missing pages, repeated uploads, conflicting fields and destination errors. Your team checks the review experience and receives instructions for correcting a record, resubmitting a file and updating the supported field set.
No account layer between you and them. These are the Norml specialists this work runs through.
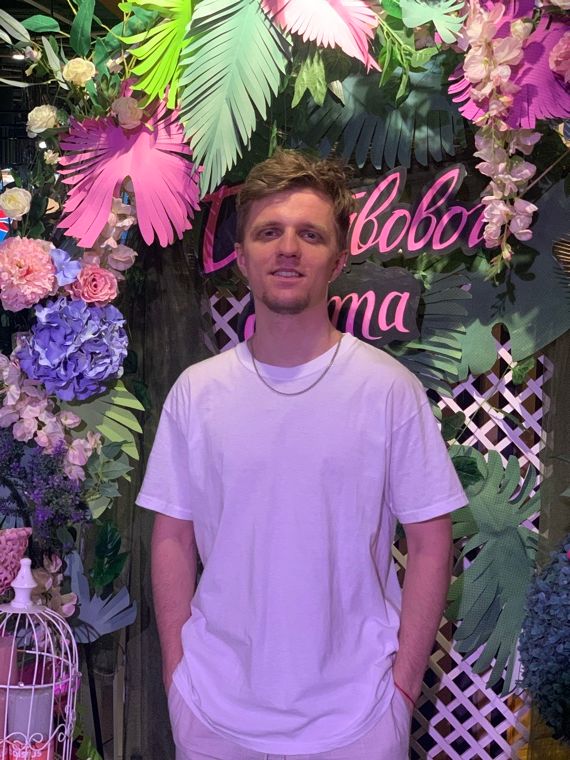
Founder & Architect
DevOps & Backend Developer
Full-Stack Developer
“I've spent 10 years working across development and marketing. I started as a developer, but design, SEO and advertising were already part of the job. That taught me to treat a website as one system: the business, the content, the design and the code have to work together. At Norml, I lead the architecture behind our work and stay involved wherever strategy, design, development and search meet.”
Max TymoshynFounder & Architect
Get started