Hours come back to your team
Work that is repetitive, rule-based and high-volume is where automation pays, and it is found by measuring the process you run today.
An intake folder can contain several jobs: an application to review, a contract to file, or a form whose fields need extracting. Norml builds AI document classification for that first decision. We define the document classes with your team, test representative files and route the results to named queues. Files that do not meet the agreed routing checks stay available for a person to inspect.
A few clients we’ve worked with

Classify incoming documents into agreed categories, route them to the right queue, and retain uncertain files for review before extraction or processing.
The expensive mistake is automating the wrong step convincingly. The value is real, and it comes from measuring the process before building anything.
Work that is repetitive, rule-based and high-volume is where automation pays, and it is found by measuring the process you run today.
When the routine path runs itself, the next increase in volume does not need another person watching a queue.
An automated step nobody can verify is a liability, so the review point is part of the design rather than something bolted on later.
The starting scope is a known set of document families and destinations. We retain the original file and make the routing decision traceable.
We define each class with examples and exclusions, including similar-looking documents that need different handling. Categories correspond to a business destination or next step. We test how the model handles unfamiliar material rather than assuming every unknown file will identify itself as unknown.
When an upload contains several documents, we assess whether classification should operate on the whole file, individual pages or detected document sections. Splitting behavior is configured deliberately and tested against packet examples. The original upload remains available while routing records point to the relevant pages.
Airtable can record the source, predicted class, checks and destination. Agreed thresholds and rule conflicts send a file to review. The processing record identifies which handoff completed, so a retry does not repeatedly notify an owner or submit the same pages to an extractor.
“Norml Studio's professionalism and responsiveness were impressive.”
“They were proactive in suggesting improvements we hadn't considered.”
“They delivered what they said they would, on time.”
“They focused on how to make our daily operations easier, not just on building features for the sake of it.”
“They understood that the app needed to be practical for someone sitting in a car, not just look good on a desktop.”
“Their level of dedication to the success of the project and GoPetZen's business as a whole is unique.”
Supply representative samples, confusing pairs and documents outside the intended classes. A new category needs a definition and evaluation examples before it becomes a routing destination.
Identify which queue, team or extractor receives each class. Classification must not grant someone access to a source document they are not permitted to read.
Choose who reviews unclear files and how corrections are recorded. Agree when a file must remain manual, how long it is retained and who can approve a change to the class definitions.
We compare model output with checked examples and inspect confusing categories. This establishes routing rules and review conditions based on your document set, without promising a universal accuracy figure.
We build the classification call, page-range handling and routing ledger. Each destination receives the agreed file reference and context, with permission checks and a recorded handoff result.
We test mixed uploads, blank pages, unfamiliar types and duplicate delivery events. Your team reviews corrections and learns how to pause routing when a new document format starts arriving.
No account layer between you and them. These are the Norml specialists this work runs through.
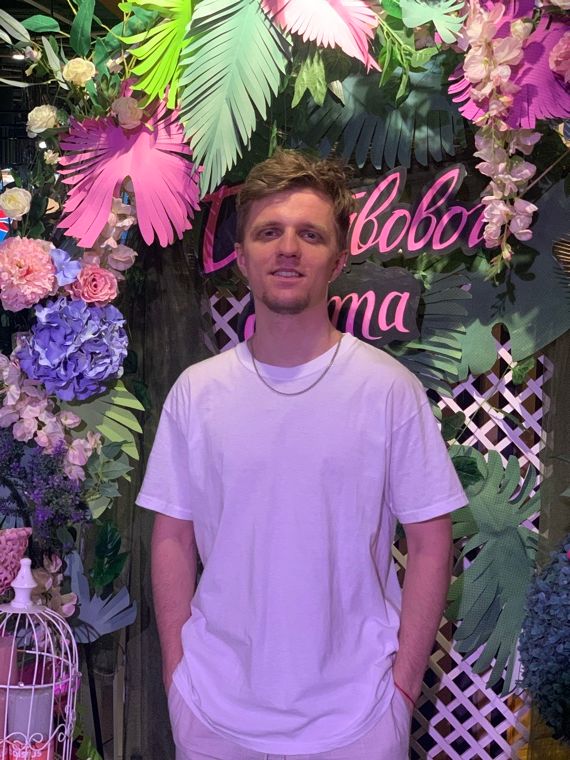
Founder & Architect
DevOps & Backend Developer
Full-Stack Developer
“I've spent 10 years working across development and marketing. I started as a developer, but design, SEO and advertising were already part of the job. That taught me to treat a website as one system: the business, the content, the design and the code have to work together. At Norml, I lead the architecture behind our work and stay involved wherever strategy, design, development and search meet.”
Max TymoshynFounder & Architect
Get started